What a Deep Web Engine Actually Does
A deep web engine operates similarly to a conventional search engine, but it is built to index content on the Tor network instead of the public internet. When you submit a search query, the engine crawls .onion addresses and returns results from pages that exist only within the Tor ecosystem. The engine itself typically runs on a hidden server and is accessed through a .onion address, meaning both the search tool and the results are anonymized.
These engines do not store personal data about your searches in the way Google does, though they may log queries for indexing purposes. The best deep web engines use minimal logging and do not correlate your searches with your IP address or identity. Some engines, like Ahmia, publish transparency reports about their operations. Understanding this distinction matters because it affects both your privacy and the reliability of the results you receive.
How Deep Web Search Differs from Surface Web Search
The core difference lies in scope and accessibility. A surface web search engine indexes pages that are publicly linked and crawlable; a deep web engine must navigate the Tor network's routing protocols and connect to servers that are intentionally hidden. This means deep web engines have a smaller index and return fewer results than Google, but those results point to content that would otherwise be invisible to you.
Another key difference is freshness. Tor hidden services change addresses frequently, mirrors go offline, and new .onion sites appear constantly. Deep web search indexes update more slowly than surface web indexes because crawling the Tor network is resource-intensive and unpredictable. When you search the best deep web links, you may encounter dead links or outdated information more often than on the surface web. This is not a flaw of the engine; it reflects the nature of the network itself.
Major Deep Web Engines and Their Characteristics
Several deep web engines have built reputations for reliability and transparency. Torch was one of the earliest and largest .onion search engines, though its current status and ownership have changed over time. Ahmia is maintained by a Finnish developer and publishes its source code, making it possible to verify its operations. Haystak indexes a large portion of the Tor network and has been relatively stable. DuckDuckGo operates on the surface web but also indexes some .onion content, offering a hybrid approach.
Each engine has different indexing policies and result quality. Some prioritize speed; others prioritize comprehensiveness. None of them are perfect, and none index the entire Tor network. When searching for top deep web information, you may need to try multiple engines to find what you are looking for. Comparing results across engines often yields better coverage than relying on a single source.
Reality Check: How Deep Web Search Actually Fails
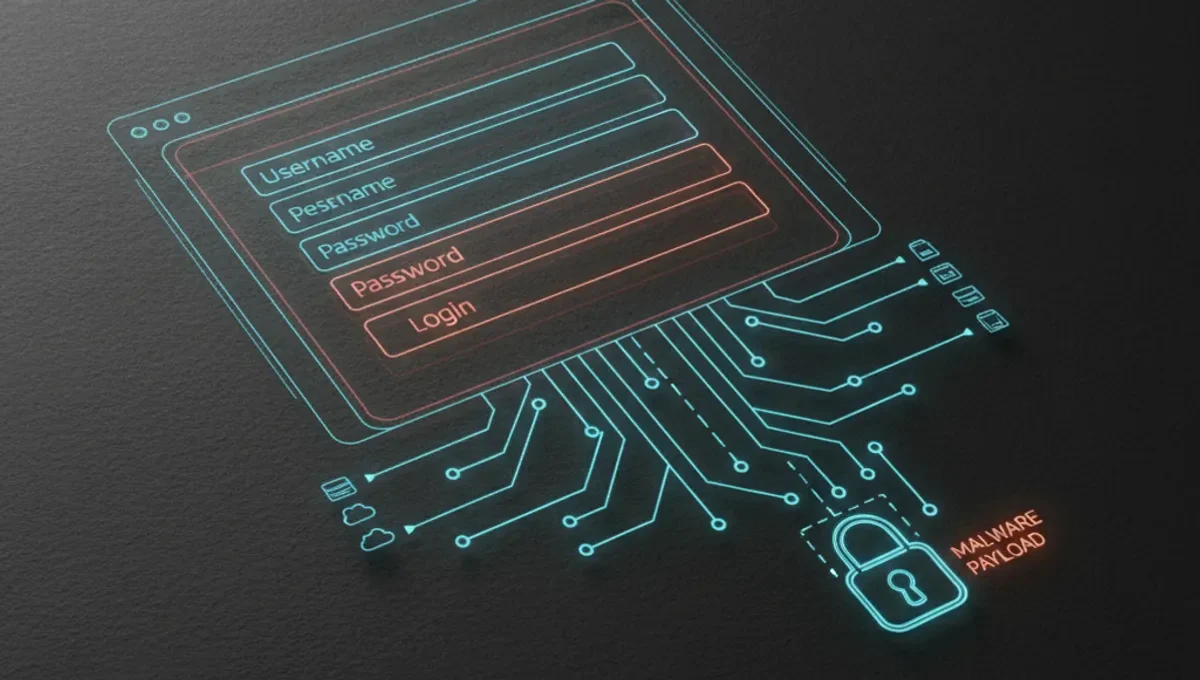
Deep web engines face several structural challenges that affect their usefulness. First, many .onion sites deliberately block search engine crawlers to maintain privacy or avoid unwanted traffic. This means a significant portion of the Tor network is never indexed, and no search engine can retrieve it. Second, phishing clones and malicious mirrors proliferate on the Tor network; a search result that looks legitimate may be a fake designed to steal credentials or distribute malware. Third, the Tor network's anonymity makes it difficult to verify the authenticity of any .onion address, so you cannot rely on a search result alone to confirm you are visiting a legitimate site.
Law enforcement agencies have also seized or disrupted several deep web search engines and the infrastructure they relied on. The Tor Project documentation emphasizes that no search engine can guarantee the safety or legality of the content it indexes. Security-vendor incident reports consistently show that users who rely solely on search results to navigate the Tor network are at higher risk of phishing and malware infection. This matters because it means you need additional verification steps beyond just clicking a search result.
Verifying Results and Avoiding Phishing Clones
When you find a result in a deep web engine, treat it as a starting point, not a confirmation of authenticity. Verify the .onion address through multiple independent sources before entering any credentials or sensitive information. Many legitimate hidden services publish their official .onion addresses on their surface web sites, in PGP-signed announcements, or through trusted community channels.
Phishing clones are nearly identical copies of popular .onion sites designed to trick you into entering your username and password. They often appear in search results because they are new mirrors or because the search engine has not yet detected them as malicious. To protect yourself:
- Always check the full .onion address in your browser's address bar, not just the search result snippet.
- Verify the address against official sources before logging in.
- Use PGP to verify signed announcements from the site operator.
- Look for HTTPS certificates and security indicators, though these are not foolproof on Tor.
- Never copy and paste a .onion address from a search result directly into your browser without visual inspection.
Setting Up Safe Search on Tor
To search the deep web safely, start by using the Tor Browser, which is the official tool maintained by the Tor Project. Tor Browser routes all your traffic through multiple Tor relays and prevents many common attacks. Once Tor Browser is open, you can access deep web engines by typing their .onion addresses directly into the address bar.
Configure your Tor Browser security settings before searching. Set the security level to Standard or higher, depending on your threat model. Disable JavaScript if you are concerned about advanced attacks, though this may break some search results. Clear your browser cache and cookies regularly, and consider using a separate Tor Browser profile for sensitive searches. Never maximize your browser window, as this can reveal your screen resolution and aid in fingerprinting. These steps reduce the risk that a malicious search result or compromised .onion site can identify you.
When to Use a Deep Web Engine and When Not To
A deep web engine is useful when you are researching legitimate hidden services, academic research on Tor, security news, or privacy-focused communities. It is also appropriate for accessing news sites and forums that operate on the Tor network to avoid censorship or surveillance in restrictive countries. However, deep web engines are not appropriate for searching for illegal goods, services or marketplaces. Such searches expose you to law enforcement attention, phishing scams, and malware.
Many people mistakenly believe that searching the deep web is inherently illegal or dangerous. In reality, the Tor network and its search engines are legal tools used by journalists, activists, and privacy-conscious individuals worldwide. The risk comes from the content you search for and the sites you visit, not from the search itself. If you are unsure whether a search or site is legal in your jurisdiction, consult local laws or a legal professional before proceeding.
Moving Forward: Search Responsibly
Using a deep web engine responsibly means understanding its limitations and combining it with other verification methods. No single search engine, whether on the surface web or the deep web, can guarantee the safety or accuracy of every result. Your role is to remain skeptical, verify independently, and use additional tools like PGP verification and trusted community resources to confirm what you find.
Start by visiting the Useful Resources page of this site to find links to official Tor Project documentation, transparency reports from deep web engines, and guides to verifying .onion addresses. If you are new to the Tor network, spend time learning how it works before relying on search results to navigate it. The time you invest in understanding the ecosystem will pay dividends in safer, more informed searches.
Frequently asked questions
Is using a deep web engine illegal
No. Using a deep web engine to search the Tor network is legal in most countries. The Tor network itself is legal and used by journalists, activists, and privacy-conscious users worldwide. What matters is what you search for and what you do with the results. Searching for illegal goods or services is illegal; searching for legitimate information is not.
Can a deep web engine find everything on Tor
No. Many .onion sites deliberately block search engine crawlers to maintain privacy. Additionally, new sites appear and old ones disappear constantly, so no engine can maintain a complete index. Deep web engines index a fraction of the Tor network, and you may need to use multiple engines or other methods to find specific content.
How do I know if a search result is a phishing clone
Verify the .onion address against official sources before logging in or entering sensitive information. Check the full address in your browser's address bar, not just the search snippet. Look for PGP-signed announcements from the site operator. If the address differs even slightly from what you expect, do not proceed.
What is the best deep web engine to use
There is no single best engine; it depends on your needs. Ahmia publishes its source code and operations transparently. Haystak indexes a large portion of the Tor network. DuckDuckGo indexes some .onion content and is accessible on the surface web. Try multiple engines and compare results to find what works best for your searches.
Can I be tracked when using a deep web engine
Using Tor Browser significantly reduces the risk of tracking, but it is not perfect. A compromised .onion site or malicious search result could attempt to identify you through browser fingerprinting or malware. Always use Tor Browser, keep it updated, and verify results independently before visiting unfamiliar sites.